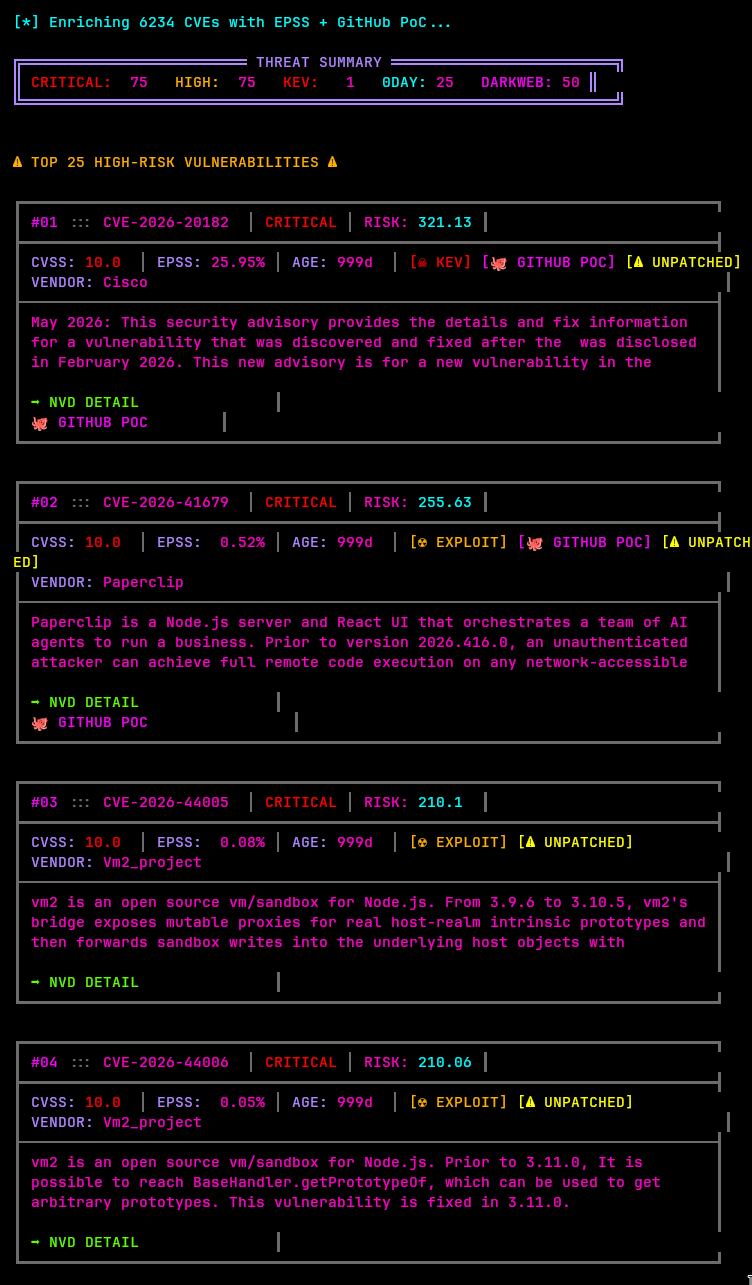
You could name this whatever you wanted as long as you are sure to include the config file. The config file should house any APIs that you call. I just wanted this to be a simple information feed. It feeds me CISA/NIST recent classifications, recently released zero-day information as the researchers release it, and recent dark web data disclosures.
I probably could have made this considerably more extensive, but you can only do so much with information. I just did this so that I could bind it to a key and have it appear whenever I wanted to. I can also have it execute automatically when I log in, or periodically throughout the day. This is another of the small things. While I do have some bigger ones coming, I have to take some time and go back through them before I open them up.
### Config File
`cat .config/scripts/config.json`
```json
{
"feed_name": "NEX-SEC-NEWS",
"nvd_api_key": "Add Your Key Here",
"github_token": "Add Your Token Here",
"lookback_days": 30,
"max_nvd_results": 25,
"max_0day_results": 25,
"epss_limit": 75,
"results_per_page": 2000,
"min_risk": 0.0,
"min_cvss": 0.0,
"watched_vendors": [
"microsoft",
"google",
"apple",
"cisco",
"oracle",
"vmware",
"citrix",
"motorola",
"android",
"ubuntu",
"arch",
"rhel"
],
"cache_enabled": true,
"cache_ttl_hours": 6
}
```
### Python Script
`cat .config/scripts/security_feed.py`
```python
import asyncio
import aiohttp
import requests
import json
import argparse
import sys
import re
import time
import textwrap
import xml.etree.ElementTree as ET
from datetime import datetime, timedelta, UTC
from pathlib import Path
from functools import lru_cache
from requests.adapters import HTTPAdapter
from urllib3.util.retry import Retry
# =========================
# CONFIGURATION MANAGEMENT
# =========================
DEFAULT_DARKWEB_RESULTS = 50
SCRIPT_DIR = Path(__file__).resolve().parent
CONFIG_PATH = SCRIPT_DIR / "config.json"
def load_config() -> dict:
if not CONFIG_PATH.exists():
print(f"[!] CONFIGURATION ERROR: Required asset 'config.json' is missing at {CONFIG_PATH}")
sys.exit(1)
try:
with open(CONFIG_PATH, "r", encoding="utf-8") as f:
user_config = json.load(f)
return user_config
except Exception as e:
print(f"[!] CONFIGURATION RUNTIME CRASH: Failed to parse 'config.json' layout schema: {e}")
sys.exit(1)
config = load_config()
FEED_NAME = config.get("feed_name", "NEX-SEC-NEWS")
NVD_API_KEY = config.get("nvd_api_key", "")
GITHUB_TOKEN = config.get("github_token", "")
LOOKBACK_DAYS = config.get("lookback_days", 30)
MAX_NVD_RESULTS = config.get("max_nvd_results", 50)
MAX_0DAY_RESULTS = config.get("max_0day_results", 50)
RESULTS_PER_PAGE = config.get("results_per_page", 2000)
EPSS_LIMIT = config.get("epss_limit", 75)
WATCHED_VENDORS = [v.lower() for v in config.get("watched_vendors", [])]
# =========================
# CLI PARAMETER RECONCILIATION
# =========================
parser = argparse.ArgumentParser(description=f"{FEED_NAME} Processing Unit")
parser.add_argument("--days", type=int, default=LOOKBACK_DAYS)
parser.add_argument("--top", type=int, default=MAX_NVD_RESULTS)
parser.add_argument("--darkweb", type=int, default=DEFAULT_DARKWEB_RESULTS)
parser.add_argument("--min-risk", type=float, default=config.get("min_risk", 0.0))
parser.add_argument("--json", action="store_true")
args = parser.parse_args()
LOOKBACK_DAYS = args.days
MAX_NVD_RESULTS = args.top
MAX_DARKWEB_RESULTS = args.darkweb
# =========================
# UTILITIES
# =========================
def sanitize(t):
if not t:
return "No description provided."
return re.sub(r'\x1B\[[0-?]*[ -/]*[@-~]', '', str(t)).replace('\n', ' ').strip()
def link(text, url):
return f"\033]8;;{url}\033\\{text}\033]8;;\033\\"
def extract_cvss(cve):
m = cve.get("metrics", {})
for k in ["cvssMetricV31", "cvssMetricV30", "cvssMetricV2"]:
if k in m and m[k]:
return m[k][0]["cvssData"].get("baseScore", 0.0)
return 0.0
def get_age_days(published_str):
try:
dt = datetime.fromisoformat(published_str.replace("Z", "+00:00"))
return (datetime.now(UTC) - dt).days
except:
return 999
def extract_vendor(cve):
try:
desc = cve["descriptions"][0]["value"].lower()
for vendor in WATCHED_VENDORS:
if vendor in desc:
return vendor.capitalize()
for config_node in cve.get("configurations", []):
for node in config_node.get("nodes", []):
for match in node.get("cpeMatch", []):
cpe = match.get("criteria", "")
if "cpe:2.3:" in cpe:
parts = cpe.split(":")
if len(parts) > 3 and parts[3]:
return parts[3].capitalize()
except:
pass
return "Unknown"
# =========================
# GITHUB POC DETECTION
# =========================
GENERIC_HEADERS = {"User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36"}
@lru_cache(maxsize=150)
def has_github_poc(cve_id: str) -> tuple[bool, str]:
year = cve_id.split("-")[1] if "-" in cve_id else ""
try:
url = f"[https://raw.githubusercontent.com/nomi-sec/PoC-in-GitHub/master/](https://raw.githubusercontent.com/nomi-sec/PoC-in-GitHub/master/){year}/{cve_id}.json"
r = requests.get(url, headers=GENERIC_HEADERS, timeout=10)
if r.status_code == 200:
data = r.json()
if data and isinstance(data, list) and len(data) > 0:
best_url = data[0].get("html_url") or data[0].get("url", "")
return True, best_url
except:
pass
if GITHUB_TOKEN:
try:
headers = {"Authorization": f"token {GITHUB_TOKEN}"}
q = f"{cve_id} (POC OR exploit OR \"proof of concept\")"
r = requests.get(
f"[https://api.github.com/search/repositories?q=](https://api.github.com/search/repositories?q=){q}&sort=stars&order=desc&per_page=5",
headers=headers, timeout=12
)
if r.status_code == 200:
items = r.json().get("items", [])
if items:
return True, items[0]["html_url"]
except:
pass
return False, ""
# =========================
# RISK ENGINE
# =========================
def calculate_risk(cvss, epss_val, is_kev, has_exploit, has_github_poc_flag, has_patch, age_days):
score = (cvss * 12) + (epss_val * 120)
if is_kev: score += 90
if has_exploit: score += 55
if has_github_poc_flag: score += 45
if not has_patch: score += 35
if age_days <= 3: score += 40
elif age_days <= 7: score += 20
return min(round(score, 2), 999)
# =========================
# DATA FETCHERS
# =========================
def build_nvd_session():
s = requests.Session()
retries = Retry(total=5, backoff_factor=1.5, status_forcelist=[429, 500, 502, 503, 504])
s.mount("https://", HTTPAdapter(max_retries=retries))
headers = {"User-Agent": "SIS-Ltd.-ThreatFeed-Forensics/4.2"}
if NVD_API_KEY:
headers["apiKey"] = NVD_API_KEY
s.headers.update(headers)
return s
nvd_session = build_nvd_session()
def fetch_zerodays():
print("[*] Fetching Zero-Day Initiative Intel...")
url = f"[https://www.zerodayinitiative.com/rss/upcoming/?t=](https://www.zerodayinitiative.com/rss/upcoming/?t=){int(time.time())}"
intel = []
try:
r = requests.get(url, headers=GENERIC_HEADERS, timeout=15)
if r.status_code == 200:
root = ET.fromstring(r.content)
for item in root.findall('./channel/item')[:MAX_0DAY_RESULTS]:
intel.append({
"title": sanitize(item.find('title').text),
"url": item.find('link').text or "",
"desc": sanitize(item.find('description').text),
"date": item.find('pubDate').text or "Unknown"
})
else:
print(f"[!] ZDI HTTP {r.status_code}")
except Exception as e:
print(f"[!] Zero-Day Fetch Error: {e}")
return intel
def fetch_darkweb_leaks():
print("[*] Fetching Dark Web Extortion & Leak Intel...")
url = "[https://data.ransomware.live/posts.json](https://data.ransomware.live/posts.json)"
intel = []
try:
r = requests.get(url, headers=GENERIC_HEADERS, timeout=15)
if r.status_code == 200:
data = r.json()
data.sort(key=lambda x: x.get('published', x.get('discovered', '')), reverse=True)
for item in data[:MAX_DARKWEB_RESULTS]:
group = item.get('group_name', 'Unknown Syndicate')
target = item.get('post_title', 'Undisclosed Target')
discovered = item.get('published', item.get('discovered', 'Unknown Date'))[:10]
intel.append({
"group": group.upper(),
"target": target,
"date": discovered,
"source_type": "DARK WEB DISCLOSURE"
})
else:
print(f"[!] Failed to fetch dark web intel. HTTP {r.status_code}")
except Exception as e:
print(f"[!] Dark Web Fetch Error: {e}")
return intel
def fetch_kev():
print("[*] Fetching CISA KEV Catalog...")
try:
r = requests.get(
"[https://www.cisa.gov/sites/default/files/feeds/known_exploited_vulnerabilities.json](https://www.cisa.gov/sites/default/files/feeds/known_exploited_vulnerabilities.json)",
headers=GENERIC_HEADERS, timeout=15
)
data = {x["cveID"]: x for x in r.json().get("vulnerabilities", [])}
return data
except Exception as e:
print(f"[!] KEV Error: {e}")
return {}
def fetch_nvd(start, end):
print(f"[*] Fetching NVD ({start} {end})...")
out = []
idx = 0
start_iso = f"{start}Z" if not start.endswith('Z') else start
end_iso = f"{end}Z" if not end.endswith('Z') else end
while True:
url = (f"[https://services.nvd.nist.gov/rest/json/cves/2.0](https://services.nvd.nist.gov/rest/json/cves/2.0)"
f"?pubStartDate={start_iso}&pubEndDate={end_iso}"
f"&resultsPerPage={RESULTS_PER_PAGE}&startIndex={idx}")
try:
r = nvd_session.get(url, timeout=25)
if r.status_code == 429:
time.sleep(30)
continue
if r.status_code != 200:
print(f"[!] NVD HTTP {r.status_code}")
break
j = r.json()
batch = j.get("vulnerabilities", [])
if not batch:
break
out.extend(batch)
idx += RESULTS_PER_PAGE
if idx >= j.get("totalResults", 0):
break
time.sleep(0.7)
except Exception as e:
print(f"\n[!] NVD Error: {e}")
break
return out
async def epss(session_async, cve_id):
try:
async with session_async.get(f"[https://api.first.org/data/v1/epss?cve=](https://api.first.org/data/v1/epss?cve=){cve_id}", timeout=10) as r:
j = await r.json()
return float(j.get("data", [{}])[0].get("epss", 0))
except:
return 0.0
# =========================
# MAIN EXECUTION VECTOR
# =========================
async def main():
now = datetime.now(UTC)
start = (now - timedelta(days=LOOKBACK_DAYS)).strftime('%Y-%m-%dT%H:%M:%S.000')
end = now.strftime('%Y-%m-%dT%H:%M:%S.000')
zero_days = fetch_zerodays()
dark_web_leaks = fetch_darkweb_leaks()
kev_map = fetch_kev()
vulns = fetch_nvd(start, end)
if not vulns:
print("[!] No recent CVEs found.")
return
vulns = sorted(vulns, key=lambda v: (extract_cvss(v["cve"]), v["cve"].get("published", "")), reverse=True)[:EPSS_LIMIT]
async with aiohttp.ClientSession(headers=GENERIC_HEADERS) as session:
epss_scores = await asyncio.gather(*[epss(session, v["cve"]["id"]) for v in vulns])
processed = []
for i, v in enumerate(vulns):
c = v["cve"]
cve_id = c["id"]
cvss = extract_cvss(c)
epss_val = epss_scores[i]
age_days = get_age_days(c.get("published", ""))
is_kev = cve_id in kev_map
refs = c.get("references", [])
has_patch = any("Patch" in r.get("tags", []) for r in refs)
has_exploit = any("Exploit" in r.get("tags", []) for r in refs)
has_poc, poc_url = has_github_poc(cve_id)
risk = calculate_risk(cvss, epss_val, is_kev, has_exploit, has_poc, has_patch, age_days)
processed.append({
"id": cve_id,
"cvss": cvss,
"epss": epss_val,
"risk": risk,
"is_kev": is_kev,
"has_exploit": has_exploit,
"has_github_poc": has_poc,
"github_poc_url": poc_url,
"has_patch": has_patch,
"age_days": age_days,
"vendor": extract_vendor(c),
"date": c.get("published", "Unknown"),
"desc": sanitize(c.get("descriptions", [{}])[0].get("value", "")),
"url": f"[https://nvd.nist.gov/vuln/detail/](https://nvd.nist.gov/vuln/detail/){cve_id}"
})
processed.sort(key=lambda x: (x["risk"], x["date"]), reverse=True)
if args.json:
with open("threat_feed_output.json", "w") as f:
json.dump(processed[:MAX_NVD_RESULTS], f, indent=2, default=str)
print("[+] Exported to threat_feed_output.json")
if __name__ == "__main__":
if sys.platform == 'win32':
asyncio.set_event_loop_policy(asyncio.WindowsSelectorEventLoopPolicy())
asyncio.run(main())
```